One portrait image
One audio recording you have permission to use
Performance direction
Animate a portrait with an audio recording you supply, creating a talking or singing photo rather than inventing a voice.
Sign in to upload files. Review your request in Vizify before sending it. Your account’s access and credit rules apply; this page does not start generation.
One portrait image
One audio recording you have permission to use
Performance direction
One video artifact
Pending until complete
One portrait image. One audio recording you have permission to use. Performance direction. Each required role must be supplied before the task can run.
Animate the attached portrait with the attached narration. Keep the person recognizable, use restrained head movement and do not change the speech.
Portrait and audio are both required. This page does not clone a voice, synthesize speech from text or guarantee exact lip or identity preservation.
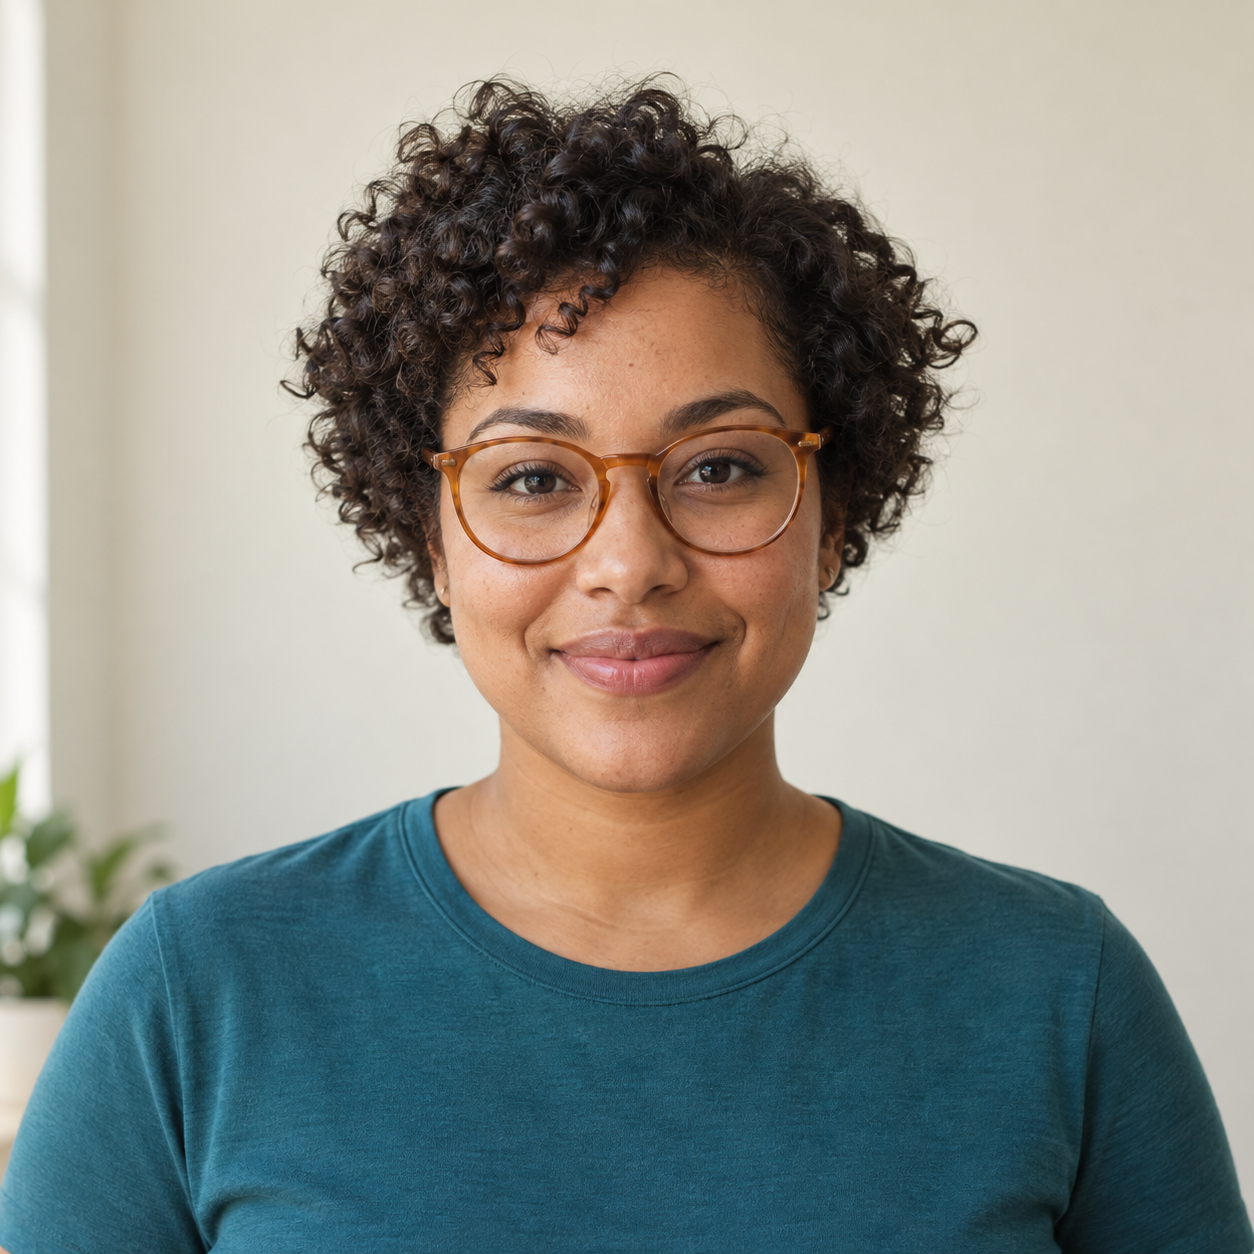
Animate the attached portrait with the attached narration. Keep the person recognizable, use restrained head movement and do not change the speech.
This example is cropped to remove garbled lettering generated on the clothing, and its tail is shortened to the narration length. The uploaded audio is unchanged.
Please attach the portrait and the speech recording, with permission to use both. Tell me who should appear to speak and any expression or framing details to preserve. No talking-photo job has been submitted, and the portrait alone does not supply the missing audio.
I want AI talking photo but have not supplied the required media. Ask me for the missing one portrait image and one audio recording you have permission to use before submitting anything.
Checks that missing inputs do not become an unrelated generation or an invented completed result.
Supply one portrait image, one audio recording you have permission to use, performance direction. The attachment picker accepts the relevant formats, but Vizify still checks whether the distinct input roles are present.
The current portrait-avatar route accepts audio up to 5 minutes; another supported expressive route is shorter. Actual support and account limits are checked in Vizify before submission.
No. Supply the finished audio you have the right to use. A talking portrait is a separate task from speech generation.
Use a clear, front-facing subject with an unobstructed mouth and adequate lighting. Review the output for identity drift and unnatural facial movement.
One PNG or JPEG portrait up to 10 MB and one MP3, WAV, OGG or M4A audio file up to 20 MB. Sign in to upload. The up-to-5-minute portrait-avatar route uses these formats; the operation is checked before submission.
AI Talking Photo is an audio or video processing task without a promised free allowance. Preparing the brief does not submit it; review the required source, your account’s paid access and credits in Vizify before sending.
No. AI Talking Photo processing is asynchronous. The one generated video artifact is a deliverable only after the task finishes, not when a request is merely accepted. Check the completed file.
Use only sources you have permission to use and inspect the entire completed result. Portrait and audio are both required. This page does not clone a voice, synthesize speech from text or guarantee exact lip or identity preservation.
Choose a portrait with a clearly visible face and a recording you have permission to use. Listen to the recording before submitting it: background speech, a clipped opening or an abrupt ending can make the result harder to assess. The transformation animates the supplied portrait with the supplied audio; it does not create a new script or clone the speaker’s voice.
Play the completed video from beginning to end. Check recognizable facial features, mouth movement, head motion and the audio ending. A convincing first frame does not establish that the whole clip is usable. If you crop or trim the result for publication, disclose the edit and keep the original for comparison. The example on this page has a cropped frame and a shortened tail; its uploaded narration is preserved.